RAG AI Knowledge Assistant
Zero-Cloud-Leakage Semantic Search & Citation-Backed LLM Q&A System
Executive Overview
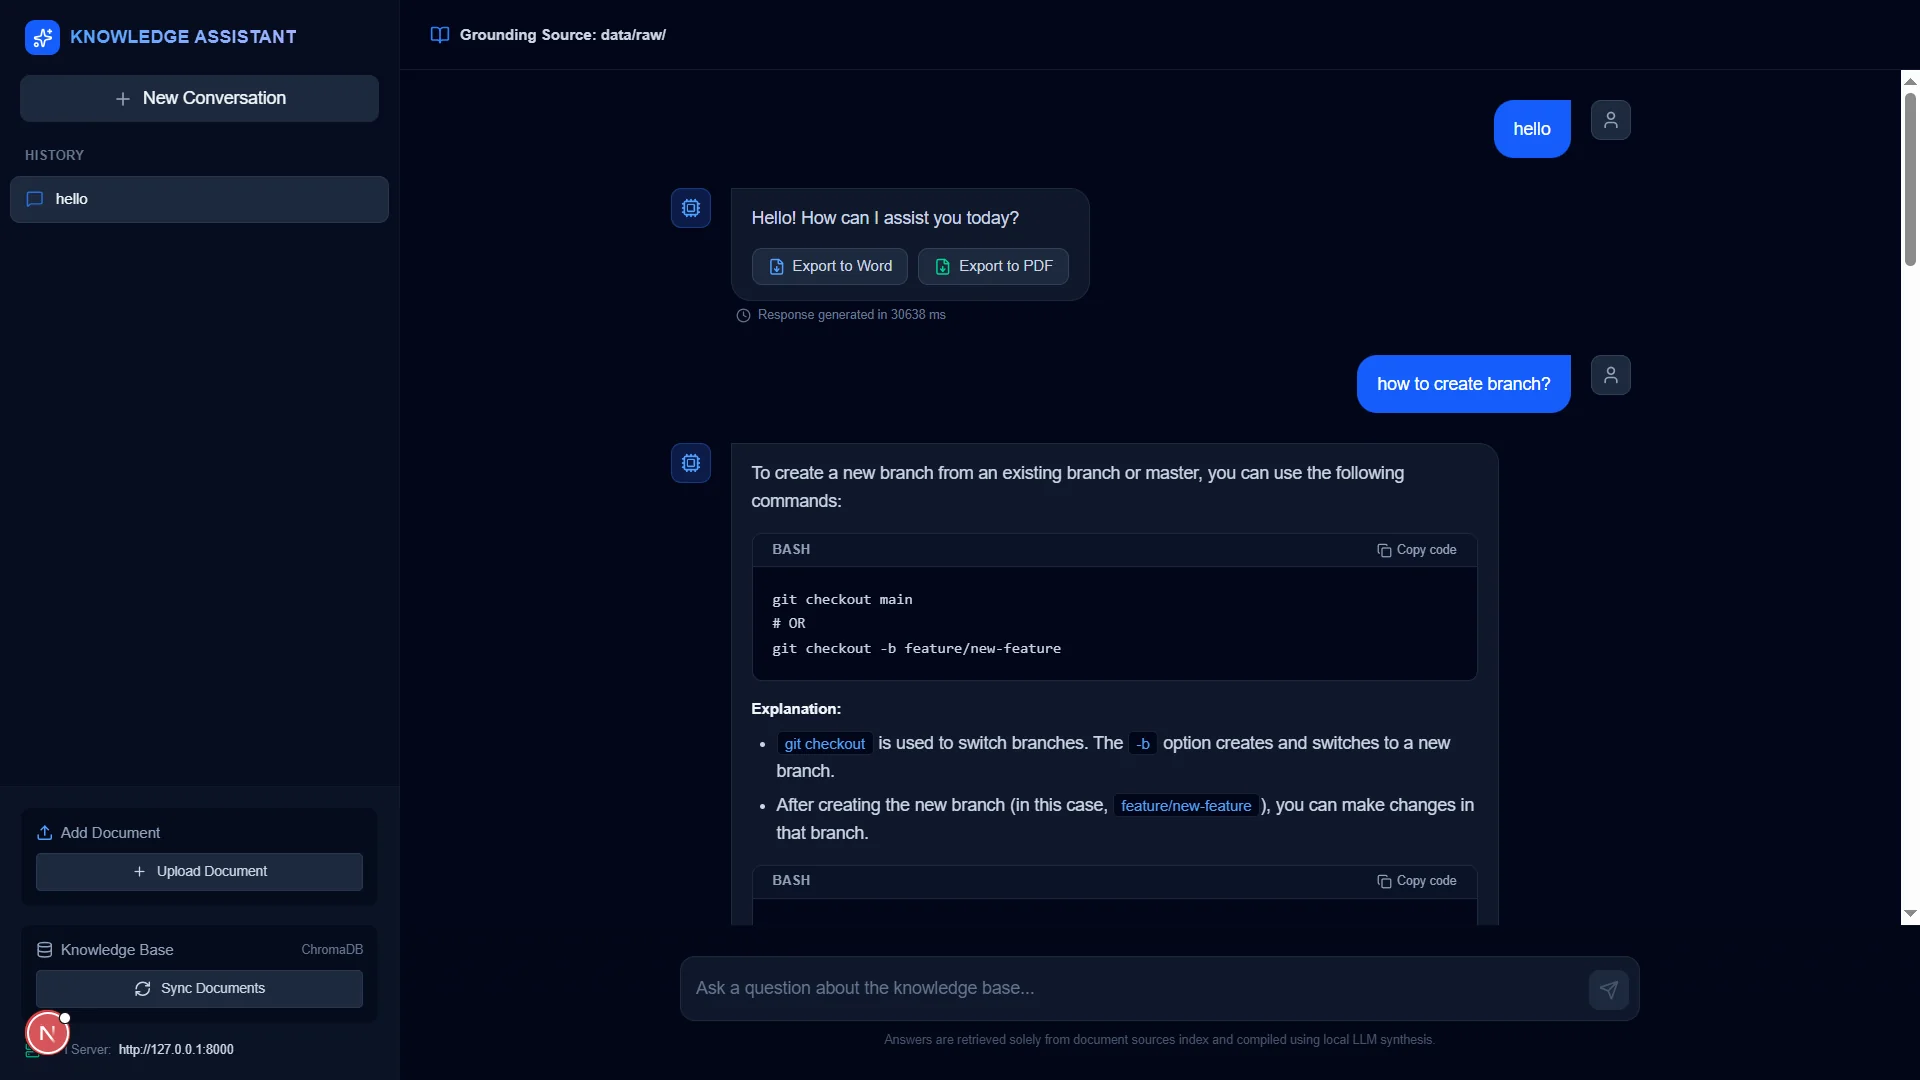
AI Knowledge Assistant is a self-hosted, air-gapped Retrieval-Augmented Generation (RAG) platform. Designed for privacy-conscious organizations, legal teams, and researchers, it ingests multi-format documents (PDF, DOCX, Markdown, TXT), creates high-dimensional vector embeddings stored locally in ChromaDB, and queries local LLMs via Ollama to generate exact, citation-backed answers without ever sending sensitive data to third-party cloud APIs.
The Challenge & Solution
Challenge: Standard enterprise LLM chatbots (like ChatGPT) risk data leakage when ingesting confidential documents. Furthermore, generic LLMs frequently hallucinate facts when asked specific questions about organizational policies, technical specifications, or financial reports.
Engineered Solution: Architected an air-gapped system combining ChromaDB dense vector indexing with Ollama-powered open weights (Qwen 2.5 / Llama 3). Enforced strict prompt boundaries requiring the model to cite exact document IDs, page numbers, and snippet quotes for every claim, with one-click Word and PDF report generation.
Technical Pipeline Breakdown
How data flows through the system from raw ingestion to production insights
Multi-Format Ingestion & Smart Chunking
Parses PDFs, DOCX, and text using recursive character splitters with contextual overlap to preserve semantic continuity across paragraph boundaries.
Dense Vector Embeddings & ChromaDB
Generates 384-dimensional dense semantic vectors using sentence-transformers, indexed into a persistent local ChromaDB instance with HNSW indexing.
Hybrid Semantic Retrieval & Re-Ranking
Performs cosine similarity search against user queries, retrieving top-k relevant chunks with cosine distance filtering to discard irrelevant noise.
Citation-Constrained LLM Inference
Constructs contextual prompts injected into local Ollama models (Qwen 2.5 / Llama 3), enforcing strict inline [Doc X, Page Y] citations and exporting executive reports.
Key Engineering Achievements
- ✓100% private and on-premise: zero telemetry, zero cloud data transfer, zero API subscription costs.
- ✓Deterministic citation verification ensures every statement references a real document sentence.
- ✓Clean Next.js 14 reactive web interface with drag-and-drop file upload, collection management, and streaming responses.
- ✓Automated executive report export generating formatted DOCX and PDF summaries with reference bibliographies.